本文介绍知识蒸馏技术及基于PaddleNLP加载CPM-Distill模型实现文本生成。知识蒸馏是模型压缩方法,以“教师-学生网络”思想,让简单模型拟合复杂模型输出,效果优于从头训练。CPM-Distill由GPT-2 Large蒸馏得到,文中还给出安装依赖、加载模型、解码方法及文本生成示例。
☞☞☞AI 智能聊天, 问答助手, AI 智能搜索, 免费无限量使用 DeepSeek R1 模型☜☜☜
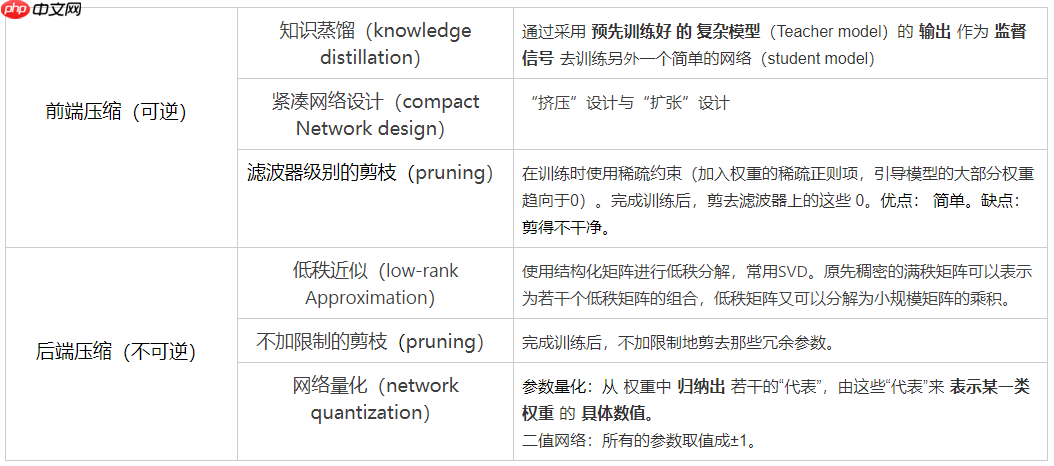
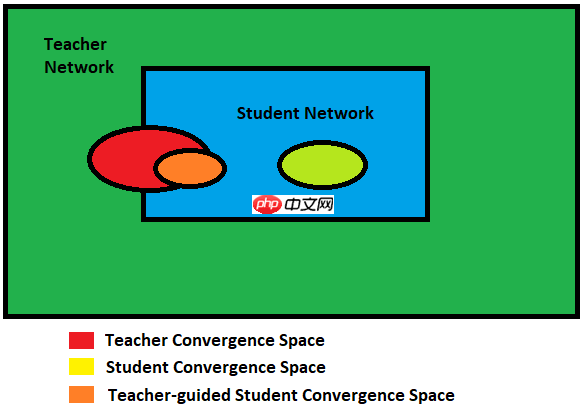
知识蒸馏是一种模型压缩方法,是一种基于“教师-学生网络思想”的训练方法。
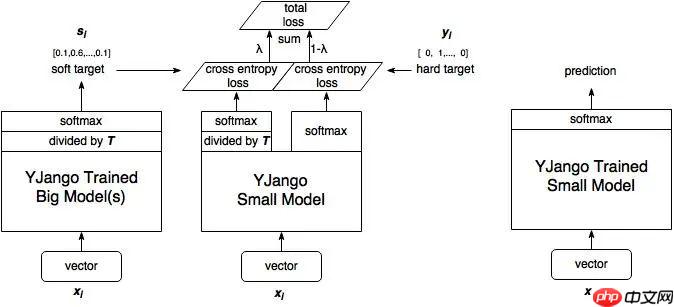
由 Hinton 在 2015 年 Distilling the Knowledge in a Neural Network 的论文首次提出了知识蒸馏的并尝试在 CV 领域中使用,旨在把大模型学到的知识灌输到小模型中,以达到缩小模型的目标,示意图如下:
 m*en使用方法 中文WORD版
本文档主要讲述的是m*en使用方法;M*en是基于项目对象模型的(pom),可以通过一小段描述信息来管理项目的构建,报告和文档的软件项目管理工具。M*en将你的注意力从昨夜基层转移到项目管理层。M*en项目已经能够知道 如何构建和捆绑代码,运行测试,生成文档并宿主项目网页。希望本文档会给有需要的朋友带来帮助;感兴趣的朋友可以过来看看
 0
查看详情

teacher_model = GPTModel(
    vocab_size=30000,
    hidden_size=2560,
    num_hidden_layers=32,
    num_attention_heads=32,
    intermediate_size=10240,
    hidden_act="gelu",
    hidden_dropout_prob=0.1,
    attention_probs_dropout_prob=0.1,
    max_position_embeddings=1024,
    type_vocab_size=1,
    initializer_range=0.02,
    pad_token_id=0,
topo=None)teacher_model = GPTModel(
vocab_size=30000,
hidden_size=768,
num_hidden_layers=12,
num_attention_heads=12,
intermediate_size=3072,
hidden_act="gelu",
hidden_dropout_prob=0.1,
attention_probs_dropout_prob=0.1,
max_position_embeddings=1024,
type_vocab_size=1,
initializer_range=0.02,
pad_token_id=0,
topo=None)
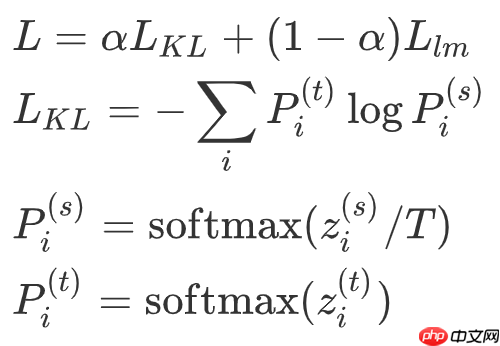
其中 Llm 为 GPT-2 原始的 language modeling loss。
!pip install paddlenlp==2.0.1 sentencepiece==0.1.92
import paddlefrom paddlenlp.transformers import GPTModel, GPTForPretraining, GPTChineseTokenizer# tokenizer 与 CPM-LM 模型一致tokenizer = GPTChineseTokenizer.from_pretrained('gpt-cpm-large-cn')# 实例化 GPT2-small 模型gpt = GPTModel(
    vocab_size=30000,
    hidden_size=768,
    num_hidden_layers=12,
    num_attention_heads=12,
    intermediate_size=3072,
    hidden_act="gelu",
    hidden_dropout_prob=0.1,
    attention_probs_dropout_prob=0.1,
    max_position_embeddings=1024,
    type_vocab_size=1,
    initializer_range=0.02,
    pad_token_id=0,
    topo=None)# 加载预训练模型参数params = paddle.load('data/data92160/gpt-cpm-small-cn-distill.pdparams')# 设置参数gpt.set_dict(params)# 使用 GPTForPretraining 向模型中添加输出层model = GPTForPretraining(gpt)# 将模型设置为评估模式model.eval()
[2025-05-28 19:38:04,469] [ INFO] - Found /home/aistudio/.paddlenlp/models/gpt-cpm-large-cn/gpt-cpm-cn-sentencepiece.model
import paddleimport numpy as np# Greedy Searchdef greedy_search(text, max_len=32, end_word=None):
    # # 终止标志
    if end_word is not None:
        stop_id = tokenizer.encode(end_word)['input_ids']
        length = len(stop_id)    else:
        stop_id = [tokenizer.eod_token_id]
        length = len(stop_id)
    # 初始预测
    ids = tokenizer.encode(text)['input_ids']
    input_id = paddle.to_tensor(np.array(ids).reshape(1, -1).astype('int64'))
    output, cached_kvs = model(input_id, use_cache=True)
    next_token = int(np.argmax(output[0, -1].numpy()))
    ids.append(next_token)    # 使用缓存进行继续预测
    for i in range(max_len-1):
        input_id = paddle.to_tensor(np.array([next_token]).reshape(1, -1).astype('int64'))
        output, cached_kvs = model(input_id, use_cache=True, cache=cached_kvs)
        next_token = int(np.argmax(output[0, -1].numpy()))
        ids.append(next_token)        # 根据终止标志停止预测
        if ids[-length:]==stop_id:            if end_word is None:
               ids = ids[:-1]            break

    return tokenizer.convert_ids_to_string(ids)
In [39]
import paddleimport numpy as np# top_k and top_p filteringdef top_k_top_p_filtering(logits, top_k=0, top_p=1.0, filter_value=-float('Inf')):
    """ Filter a distribution of logits using top-k and/or nucleus (top-p) filtering
        Args:
            logits: logits distribution shape (vocabulary size)
            top_k > 0: keep only top k tokens with highest probability (top-k filtering).
            top_p > 0.0: keep the top tokens with cumulative probability >= top_p (nucleus filtering).
                Nucleus filtering is described in Holtzman et al. (http://arxiv.org/abs/1904.09751)
        From: https://gist.github.com/thomwolf/1a5a29f6962089e871b94cbd09daf317
    """
    top_k = min(top_k, logits.shape[-1])  # Safety check
    logits_np = logits.numpy()    if top_k > 0:        # Remove all tokens with a probability less than the last token of the top-k
        indices_to_remove = logits_np < np.sort(logits_np)[-top_k]
        logits_np[indices_to_remove] = filter_value    if top_p < 1.0:
        sorted_logits = paddle.sort(logits, descending=True)
        sorted_indices = paddle.argsort(logits, descending=True).numpy()
        cumulative_probs = paddle.cumsum(paddle.nn.functional.softmax(sorted_logits, axis=-1), axis=-1).numpy()        # Remove tokens with cumulative probability above the threshold
        sorted_indices_to_remove = cumulative_probs > top_p        # Shift the indices to the right to keep also the first token above the threshold
        sorted_indices_to_remove[..., 1:] = sorted_indices_to_remove[..., :-1]
        sorted_indices_to_remove[..., 0] = 0

        indices_to_remove = sorted_indices[sorted_indices_to_remove]
        logits_np[indices_to_remove] = filter_value    return paddle.to_tensor(logits_np)# Nucleus Sampledef nucleus_sample(text, max_len=32, end_word=None, repitition_penalty=1.0, temperature=1.0, top_k=0, top_p=1.0):
    # 终止标志
    if end_word is not None:
        stop_id = tokenizer.encode(end_word)['input_ids']
        length = len(stop_id)    else:
        stop_id = [tokenizer.eod_token_id]
        length = len(stop_id)    # 初始预测
    ids = tokenizer.encode(text)['input_ids']
    input_id = paddle.to_tensor(np.array(ids).reshape(1, -1).astype('int64'))
    output, cached_kvs = model(input_id, use_cache=True)
    next_token_logits = output[0, -1, :]    for id in set(ids):
        next_token_logits[id] /= repitition_penalty
    next_token_logits = next_token_logits / temperature
    filtered_logits = top_k_top_p_filtering(next_token_logits, top_k=top_k, top_p=top_p)
    next_token = paddle.multinomial(paddle.nn.functional.softmax(filtered_logits, axis=-1), num_samples=1).numpy()
    ids += [int(next_token)]    # 使用缓存进行继续预测
    for i in range(max_len-1):
        input_id = paddle.to_tensor(np.array([next_token]).reshape(1, -1).astype('int64'))
        output, cached_kvs = model(input_id, use_cache=True, cache=cached_kvs)
        next_token_logits = output[0, -1, :]        for id in set(ids):
            next_token_logits[id] /= repitition_penalty
        next_token_logits = next_token_logits / temperature
        filtered_logits = top_k_top_p_filtering(next_token_logits, top_k=top_k, top_p=top_p)
        next_token = paddle.multinomial(paddle.nn.functional.softmax(filtered_logits, axis=-1), num_samples=1).numpy()
        ids += [int(next_token)]        # 根据终止标志停止预测
        if ids[-length:]==stop_id:            if end_word is None:
               ids = ids[:-1]            break

    return tokenizer.convert_ids_to_string(ids)
# 输入文本inputs = input('请输入文本:')print(inputs)# 使用 Nucleus Sample 进行文本生成outputs = greedy_search(
    inputs, # 输入文本
    max_len=128, # 最大生成文本的长度
    end_word=None)# 打印输出print(outputs)
请输入文本:请在此处输入你的姓名 请在此处输入你的姓名,然后点击“确定”,就可以开始游戏了。 游戏目标:在限定时间内,成功地把所有的牌都通通打完。In [43]
# 输入文本inputs = input('请输入文本:')print(inputs)for x in range(5):    # 使用 Nucleus Sample 进行文本生成
    outputs = nucleus_sample(
        inputs, # 输入文本
        max_len=128, # 最大生成文本的长度
        end_word='。', # 终止符号
        repitition_penalty=1.0, # 重复度抑制
        temperature=1.0, # 温度
        top_k=3000, # 取前k个最大输出再进行采样
        top_p=0.9 # 抑制概率低于top_p的输出再进行采样
    )    # 打印输出
    print(outputs)
请输入文本:请在此处输入你的姓名 请在此处输入你的姓名、学校、专业及学科,并在社交媒体上公布你的个人简介。 请在此处输入你的姓名或者电话,对方会及时通知你。 请在此处输入你的姓名、民族及籍贯信息,当您找到 CADULI 的联系方式后,我们会按您所选择的申请中心,以电子邮件的形式向您发送邮件。 请在此处输入你的姓名和电话号码,由资深*接待员进行介绍,因为此处有不少中国的大老板,英文能看。 请在此处输入你的姓名、联系电话、银行卡号和手机号。
以上就是CPM-Distill:经过知识蒸馏的小型文本生成模型的详细内容,更多请关注其它相关文章!
# 一键
# SEO优化腾翔科技
# 资金盘 推广网站
# 邵阳律师网站推广
# 做平台推广怎么建网站的
# seo外链的误区
# 查找关键词排名的方法
# 亳州网站建设网络推广
# 渝中区图书馆网站建设
# 零售品牌如何营销推广
# 青岛网站优化分析公司
# 安装包
# 的是
# git
# 是一种
# 文档
# 加载
# 请输入
# 中文网
# 请在
# type
# udio
# red
# 压缩技术
# ai
# cad
相关栏目:
【
Google疑问12 】
【
Facebook疑问10 】
【
优化推广96088 】
【
技术知识133117 】
【
IDC资讯59369 】
【
网络运营7196 】
【
IT资讯61894 】
相关推荐:
在这里见未来!杭州未来科技城全球AI盛会邀您共探最前沿
智能机器人正在彻底改变客户服务
阿里达摩院向公众免费开放100项AI专利许可
360发布认知型通用大模型“360智脑4.0” 全面接入360全家桶
WAIC 2025|云深处科技绝影Lite3与X20四足机器人亮相
人工智能赋能广西自然资源领域监测监管
人工智能产业协同创新中心:全产业链资源在这里汇聚
今年,全球客服中心支出将增长 16.2%,迎接对话式 AI 的浪潮,根据 Gartner 报告
华为联合合作伙伴 共同发布昇腾AI大模型训推一体化解决方案
对话无界AI创始人长铗:AI的创业机会在应用层丨创新者Innovator
Meta将VR头显最低年龄限制从13岁降至10岁
无需照相馆,AI证件照生成软件即将推出
OpenAI已向中国申请注册“GPT-5”商标,此前已在美国提交申请
北京市通用人工智能产业创新伙伴计划名单公布,京东科技入选“算力伙伴”
湖北科技职业学院举行工业机器人及智能制造技术专精特新产业学院建设启动仪式
谷歌借AI打破十年排序算法封印,每天被执行数万亿次,网友却说是最不切实际的研究?
中国联通推出“极光一号”5G机载终端,适配大疆等品牌无人机设备
人工智能助力精准学习,猿辅导小猿学练机满足学生个性化学习需求
人工智能正在弥合认知和表达之间的鸿沟
“上海市民营企业人工智能赋能创新中心”揭牌成立
苹果头显降临,AI虚拟人的救星还是流星?
尼康尼克尔 Z 180-600mm f/5.6-6.3 VR 镜头发布,12499 元
塑造全能智能管家:华为小艺AI加成应对大模型挑战
AI取代人工先拿教育行业开刀?美版“作业帮”启动裁员
抢占新赛道 加快机器人产业集聚发展
绿联发布笑脸屏幕显示充电状态的30W/65W Q湃机器人充电器
VR健身应用《FitXR》将取消Quest 1端会员服务
机构:边缘AI或是当前预期差最大的AI方向
长宁这家企业在世界人工智能大会上荣获“蓝鼎奖”
物联网“僵尸网络DDos攻击”增长惊人,威胁全球电信网络
Meta发布语音AI模型 Voicebox 助虚拟助手与NPC对话
放弃自动驾驶,也是一种和解
2025 WAIC|美团无人机发布第四代新机型
“图壤·阅读元宇宙”亮相北京国际图书博览会
烟台大学学生首次在全国大学生无人机航拍竞赛中获奖
Gartner预测:到2025年,全球对话式人工智能支出预计将达到1860亿美元
DeepMind推惊世排序算法,C++库忙更新!
马斯克WAIC2025演讲全文:AI将对人类文明产生深远影响
击败LLaMA?史上超强「猎鹰」排行存疑,符尧7行代码亲测,LeCun转赞
埃森哲俞毅:AI时代我们需要新的“摩尔定律”
马斯克回应“人工智能让一切变得更好”:我们已经是半机器人了
Meta开源文本生成音乐大模型,我们用《七里香》歌词试了下
复旦发布「新闻推荐生态系统模拟器」SimuLine:单机支持万名读者、千名创作者、100+轮次推荐
人工智能写作检测工具不靠谱,美国宪法竟被认为是机器人写的
朝鲜出现国产大型察打一体无人机,实力世界第二,太意外了
比尔盖茨:AI确实存在风险,但可控
学而思推出AI第一课:基于自研大模型的AIGC课程
谷歌旗下 DeepMind 开发出 RoboCat AI 模型,能控制多种机器人执行一系列任务
有远见!华为四年前注册商标Vision Pro:苹果AR国内要改名
杭州举办第19届亚运会,主题为「亚运元宇宙」的发布仪式举行
2025-07-18

运城市盐湖区信雨科技有限公司是一家深耕海外推广领域十年的专业服务商,作为谷歌推广与Facebook广告全球合作伙伴,聚焦外贸企业出海痛点,以数字化营销为核心,提供一站式海外营销解决方案。公司凭借十年行业沉淀与平台官方资源加持,打破传统外贸获客壁垒,助力企业高效开拓全球市场,成为中小企业出海的可靠合作伙伴。

 入你的姓名、民族及籍贯信息,当您找到 CADULI 的联系方式后,我们会按您所选择的申请中心,以电子邮件的形式向您发送邮件。
请在此处输入你的姓名和电话号码,由资深*接待员进行介绍,因为此处有不少中国的大老板,英文能看。
请在此处输入你的姓名、联系电话、银行卡号和手机号。